Company News · September 30, 2026
Eight AMD Instinct MI350P cards in one server, and what they are for
velia.net has ordered an 8-GPU AMD Instinct MI350P server.
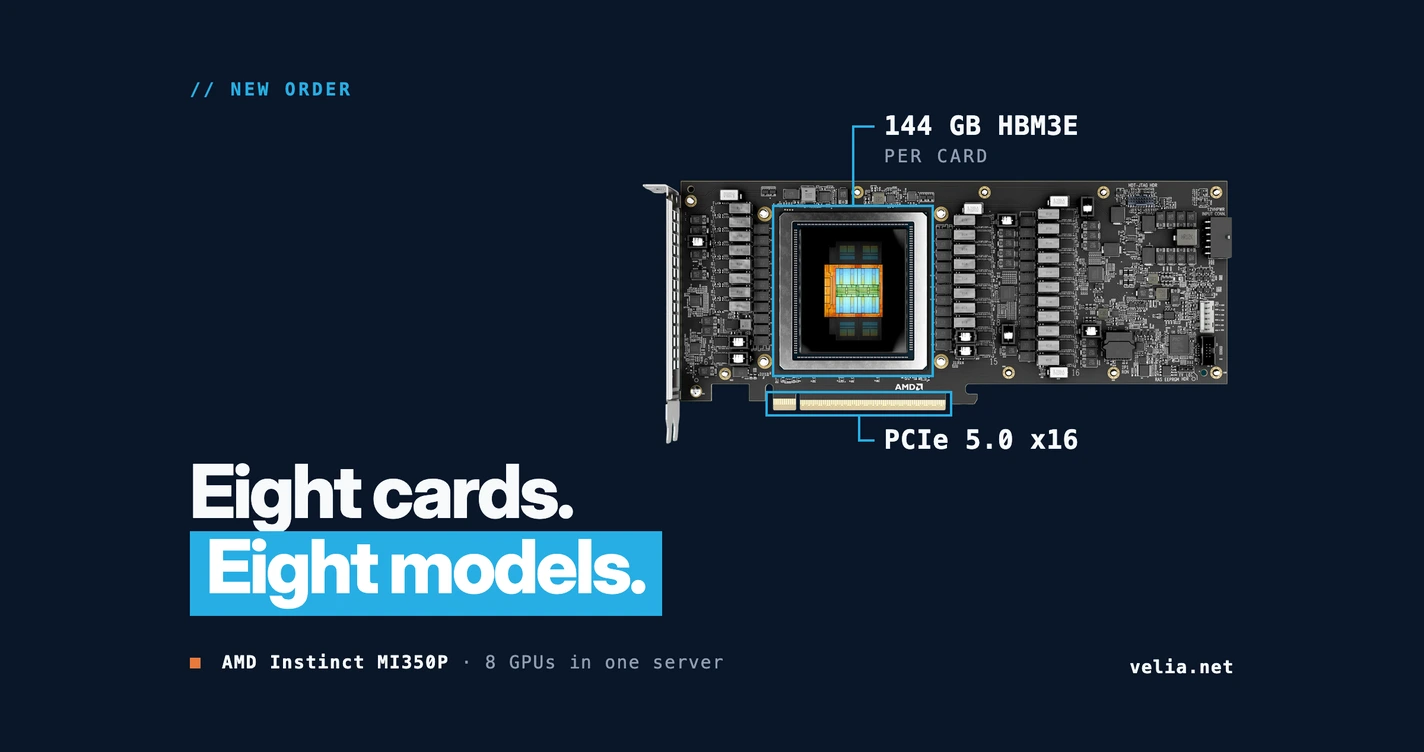
If your AI stack is a chat model, an embedding model and a reranker, you are running three models, not one. This server is built for that shape of work: one model per card, eight cards, and 144 GB of HBM3E memory on each card.
Talk to the teamWhat the AMD Instinct MI350P is.
The MI350P is the PCIe card in AMD's Instinct MI350 Series, built on AMD's CDNA 4 architecture. AMD describes it as a full-height, full-length, dual-slot card with passive cooling that connects to the server over one PCIe 5.0 x16 link. It is designed for air-cooled servers, with up to eight cards per server.
Each card carries 144 GB of HBM3E memory. AMD rates the board at up to 600 W, and it can be set down to 450 W where power or cooling is tight.
AMD positions the card for AI inference and RAG pipelines in existing data centers. Inference is a trained model answering requests. RAG, retrieval-augmented generation, is a model that looks things up in your own documents before it answers.
How the eight cards talk to each other.
AMD builds the MI350 Series in two physical shapes. The MI350X and MI355X are OAM modules, short for OCP Accelerator Module, mounted eight to a baseboard. AMD documents those systems as fully connected: every GPU links directly to the other seven through seven AMD Infinity Fabric links, next to its PCIe link to the host.
The MI350P is the other shape. AMD lists a single interconnect for it, one PCIe 5.0 x16 link to the host.
The server velia.net ordered uses the MI350P, the PCIe card, not the OAM modules.
Why one model per card.
Splitting one large model across several GPUs means the cards exchange intermediate results again and again while the model runs. On the OAM systems that traffic has a fabric of its own: seven Infinity Fabric links per GPU, which AMD rates at over 1 TB/s of aggregate bandwidth per GPU. For the MI350P, AMD lists one PCIe 5.0 x16 link at 128 GB/s, and that one link is also the card's connection to the host.
So we describe this server as one model per card, not one model across eight.
What this server is good for.
Several models side by side, one per card.
When a model fits into the 144 GB on its own card, that card does not need to talk to the other seven. How the cards connect to each other stops mattering, because nothing has to cross between them.
That fits a lot of inference work. Separate language models for separate teams or products. A chat model next to the embedding and reranking models a RAG pipeline needs.
Where it is a weaker fit.
One model too big for a single card's 144 GB, split across several cards. The cards then share data over PCIe, which is slower than the direct GPU links of the OAM versions.
What velia.net sells today.
One physical machine, rented by the month, with no other customer on it. No hypervisor between the workload and the metal, and no shared tenancy. In business since 2003.
Price, location and date are not published yet.
Book time with the teamFrequently Asked Questions
How much memory does each card have.
AMD lists 144 GB of HBM3E memory per MI350P card.
Can the eight cards work together on one model.
They can exchange data over PCIe 5.0. AMD lists one interconnect per MI350P card, a PCIe 5.0 x16 link at 128 GB/s, against over 1 TB/s of aggregate GPU-to-GPU bandwidth per GPU on the OAM versions. That is why we describe this server as one model per card.
Is it a training server.
AMD positions the MI350P for inference and RAG pipelines.
How will the server be offered.
Price, location and date are not published yet.
Eight cards, eight models, each one on a card of its own.
Dedicated Servers
Enterprise bare metal built for demanding workloads. No noisy neighbors, no virtualization overhead.
See Server Plans